Anthropic has rolled out Claude Fable 5.1, its latest frontier model explicitly engineered for extended reasoning, multi-stage research, and complex coding tasks. Instead of just responding to prompts, it can plan actions, use tools, verify results, and adapt its approach to achieve a goal.
With Fable 5.1, Anthropic also introduced Claude Mythos 5.1, an invite-only version for vetted organizations. In this article, let’s explore what is Claude Fable 5.1, it’s features, use cases, benchmarks, pricing, and what sets it apart from conventional AI models.
Understanding Claude Mythos 5.1
Claude Mythos 5.1 is the same as Fable 5.1 but with more lenient safeguards, and it is available only through Anthropic’s trusted access programs. Claude Mythos 5.1 is neither a bigger model nor an altered architecture. Anthropic has officially released the pricing for Mythos 5.1, and it is identical to Fable 5.1. It costs $10 per million input tokens and $50 per million output tokens. The only difference is its capabilities, due to the safeguards allowed.
Access is currently available to a limited number of organizations in the United States, with Anthropic working to expand it.
- The Life Sciences Verification Program provides vetted researchers with access to reduced safeguards for advanced biological research.
- Anthropic also has a Cyber Verification Program for vetted defensive security work, which is expected to include access to Mythos 5.1.
The difference shows up in coding: Claude Mythos 5.1 scores 60.9% on Terminal-Bench 4.0, while Claude Fable 5.1 scores 55.8%. Claude Security, the tool developed by Anthropic to scan codebases and suggest human-reviewable patches, is now supported by Mythos 5.1.
Understanding Claude Fable 5.1
Claude Fable 5.1 is Anthropic’s cutting-edge model for work that requires extensive reasoning and task execution. Anthropic specifically recommends the model for tough reasoning and long-horizon agentic work, while the documentation highlights better performance in long-coding, multi-stage research, and document, spreadsheet, and slide tasks.
Fable 5.1 is a multimodal model (accepts text and images, produces text) with an enormous context window of 1 million tokens and can produce up to 128,000 output tokens in one response. Its knowledge cutoff is June 2026.
One characteristic of Fable 5.1 is ‘adaptive thinking.’ This means the model constantly checks its reasoning process, and users can manually set the amount of effort. The default setting for effort is High for Fable 5.1 (Claude Code) and Medium for Claude Cowork and Claude AI.
What Is New In Claude Fable 5.1?
Claude Fable 5.1 extends Claude Fable 5 at the same input and output pricing, with cache reads at a quarter of the cost. It also introduces stronger long-running agentic coding, multistep research, and document, spreadsheet, and slide work.
- Most workloads generally begin with Claude Opus 5.5.
- Use Claude Fable 5.1 for long-horizon agentic work and demanding reasoning, or when your evaluations of Claude Opus 5.5 at a higher effort are still inadequate.
- Project Glasswing participants can access the same capabilities exclusively in Claude Mythos 5.1.
How is it Different From Cloud Fable 5?
Three changes are important if you are moving from Claude Fable 5 to Fable 5.1: forced tool use now results in an error, earlier Claude models cannot read Fable 5.1 thinking blocks, and editing earlier turns can invalidate thinking blocks. Fable 5.1 also adds five features: lower cache read pricing, content provenance, readable progress updates between tool calls, turn-scoped system messages, and per-message effort controls.
Thinking Block Capabilities
Thinking blocks are model-specific, and compatibility works in one direction. Claude Fable 5.1 can read thinking blocks created by Claude Opus 5, Claude Fable 5, and earlier Claude models. However, those earlier models cannot read thinking blocks created by Fable 5.1. So, a conversation can move from an earlier Claude model to Fable 5.1 while retaining those thinking blocks, but the same does not work in reverse.
Dealing With Unsupported Thinking Blocks
If a request contains a thinking block that the target model cannot read, for example, when a router or fallback switches models mid-conversation, the API removes that block before passing the request to the model. Tokens from these dropped thinking blocks are not counted as input tokens and are not billed.
Read more about what make Claude Fable 5.1 different in our blog: Claude Fable 5.1 vs Opus 5.5: Benchmarks, Cost & Verdict
Distinguishing Features of Claude Fable 5.1
Claude Fable 5.1 and Claude Mythos 5.1 are identical models; however, they have varying degrees of protection. Mythos 5.1 is exclusively accessible through Anthropic’s trusted access programs, while Fable 5.1 is generally accessible. Mythos 5.1's safeguards are specifically designed to facilitate work in the life sciences and cybersecurity.
Fable 5.1 also implements significant measures to address customer feedback regarding safeguards, data retention, and pricing, in addition to its enhanced capabilities.
Pricing
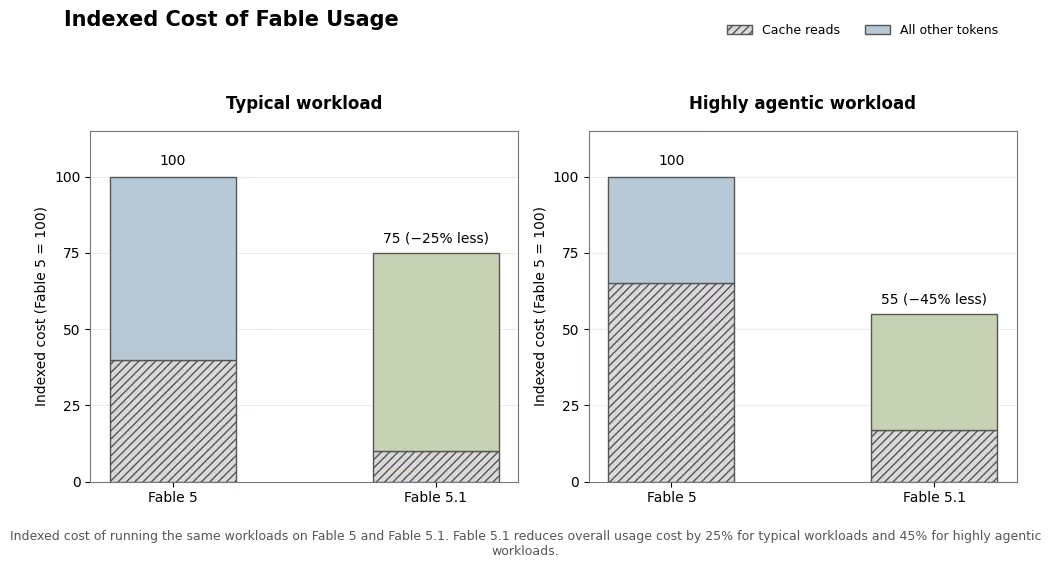
Claude Fable 5.1 pricing is set at 25% lower price than Fable 5 for typical workloads, provided that usage is billed by token. This is because pricing for cache reads is decreasing, which involves the model reading inputs that have already been processed and stored. Savings will often be much higher for highly agentic workloads, reaching up to about 45%.
Data Retention
Claude Fable 5.1 generally requires 30-day data retention and is not available under zero data retention (ZDR) arrangements unless expressly authorized by Anthropic. The company is introducing Enterprise Frontier Safeguards (EFS), which allows retained monitoring data to remain in cloud infrastructure controlled by the customer rather than Anthropic. EFS is being rolled out to enterprise customers in phases. In the meantime, eligible customers may receive temporary ZDR access to Fable 5.1.
Safeguards
Improved protections reduce false positives, which occur when the system flags harmless material. Anthropic says Claude Code users can expect around 60% fewer interventions per session from its cyber safeguards compared with the previous safeguards on Fable 5.
Fable 5.1 can now detect software vulnerabilities, but not build exploits for them, which is also a contributing factor. For example, Anthropic established a biology access effort with the US government to make Claude Mythos 5.1's sophisticated biology capabilities more accessible. Scientists can expect enrollment to begin soon.
Use Cases of Claude Fable 5.1
Claude Fable 5.1 is a Mythos-level model that has been specifically designed for your most ambitious, long-running projects. It avoids apparent shortcuts, addresses the underlying causes of issues rather than their symptoms, and provides updates as it operates.
Agents
Claude Fable 5.1 is built to deal with work that requires hours and involves several applications, like sorting through a backlog in Cowork, collecting requests in Slack via Claude Tag (beta), navigating a browser, or running as a managed agent on the Claude Platform. Claude structures the task, uses the relevant apps, recovers from mistakes, and sends updates without prompting.
Coding
Claude Fable 5.1 is Anthropic's most capable model for ambitious coding projects, with capabilities that cover the whole codebase, code reviews, performance work, and multi-day autonomous sessions. Claude can replicate designs with precision, write tests to validate itself, and employ vision to compare output to the objective.
Enterprise workflows
Claude Fable 5.1 efficiently manages intricate, multi-stage knowledge work, from in-depth research and analysis to deliverables that are prepared for your review, with minimal supervision. Rather than overseeing each step, teams can delegate large projects and evaluate completed work.
Vision
Claude Fable 5.1 enhances document-intensive work in finance, legal, analytics, and architecture by understanding diagrams, charts, and tables embedded in files and PDFs. The model also employs vision to assess its own coding efforts, comparing the outputs to the original design or objective.
Availability And Pricing
For individuals and organizations tackling their most challenging knowledge and coding tasks, Claude Fable 5.1 is available to users in Pro, Max, Team, and Enterprise tiers.
For developers building AI solutions that require cutting-edge intelligence, Claude Fable 5.1 is available through the Claude API, Amazon Bedrock, Claude Platform on AWS, Google Cloud, and Microsoft Foundry.
Claude Fable 5.1 costs $10 per million input tokens and $50 per million output tokens. Cache reads are priced at $0.25 per million tokens, down 75% from Fable 5, which means a 25% cost reduction for standard workloads and up to about 45% for highly agentic workloads.
Claude Fable 5.1 is available on:
- Claude API: all customers, as claude-fable-5-1.
- AWS: Claude in Amazon Bedrock, as anthropic.claude-fable-5-1, and Claude Platform on AWS, as claude-fable-5-1.
- Google Cloud: Claude on Google Cloud, as claude-fable-5-1.
- Microsoft Foundry: Claude in Microsoft Foundry, on Anthropic infrastructure.
Claude Fable 5.1 Benchmarks
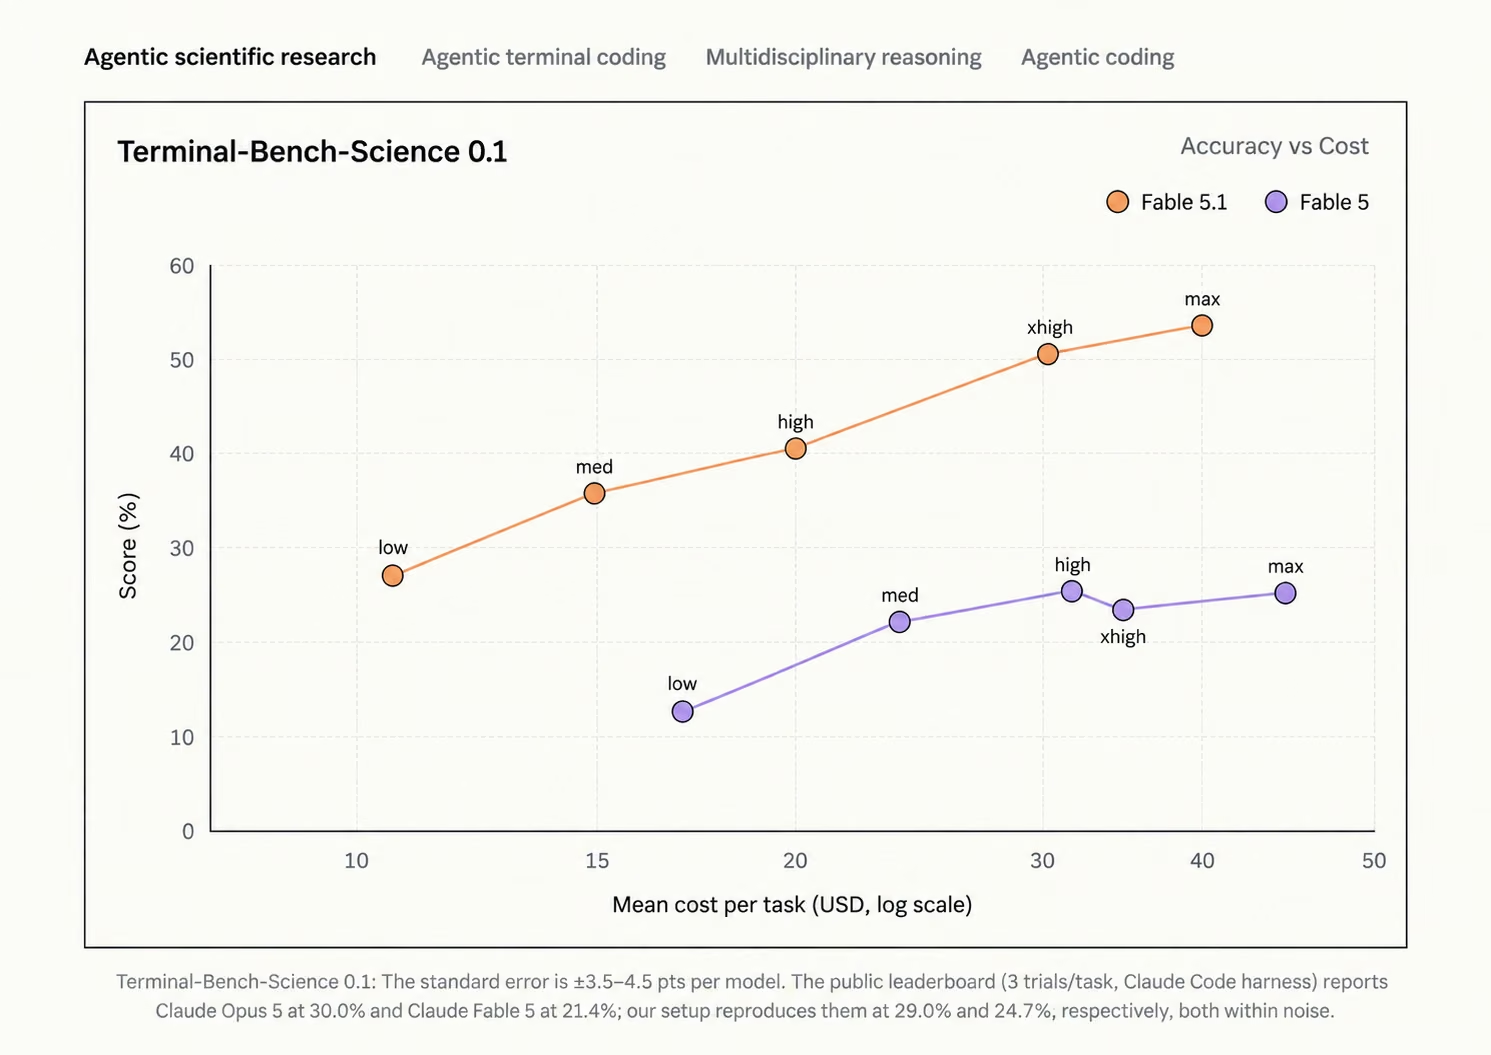
When it comes to Claude Fable 5.1 vs Fable 5, Claude Fable 5.1 shows stronger performance than Fable 5 across coding, long-running problem-solving tasks, and knowledge work. Anthropic's published benchmark results show that Fable 5.1 outperformed Fable 5 on several evaluations, including agentic scientific research, coding, knowledge work, and computer-use tasks.
Claude Fable 5.1 benchmarks also show a significant improvement on long-horizon task execution. For instance, on Terminal-Bench-Science 0.1, which evaluates agentic scientific research, Fable 5.1 achieved 52.6% accuracy compared with Fable 5's 24.7%.
Moreover, the new model can address intricate real-world tasks. The model has also shown promising results on complex real-world tasks. In testing by investment firm Millennium, Fable 5.1 identified the cause of an extremely rare crash that the firm's engineers and other models had been unable to explain. It disassembled an external vendor library, matched it against the core dump, and traced the crash to a bug in that library.
Claude Fable 5.1 is now available for use on Anthropic's Pro, Max, Team, and Enterprise plans and can be accessed via the Claude Platform, AWS (Amazon Bedrock), Google Cloud, and Microsoft Foundry.
Who Should Use Claude Fable 5.1?
Claude Fable 5.1 makes the most sense when a task requires sustained reasoning and execution rather than a quick response.
Software engineering teams: Published results show Claude Fable 5.1 scoring 78.2% on Terminal-Bench 2.0 and 72.7% on CursorBench. This shows that this model can handle more complex cases that require agentic code writing and long-term software development.
Research teams: Terminal-Bench-Science Fable 5.1 has scored 54.5% and scientific examples from Anthropic make this model applicable to coding, analysis, and long-term investigations in the research process.
Knowledge workers: A score of 1853 GDPval-AA v2, document work, research, presentation creation, and other knowledge-work evaluations make Claude Fable 5.1 relevant for complex workflows in a professional environment.
Agent builders: With a score of 73.4%, adaptive reasoning, a 1 million-token context window, a tool-oriented workflow, and cheaper cache reads make this model more relevant for multistep systems.
For a simple question, short copywriting, or a light task, a reasonably priced model can be sufficient. Claude Fable 5.1 becomes more valuable when an incomplete result would mean repeated attempts, additional supervision, or more work to get the task finished.
Conclusion
Claude Fable 5.1 is Anthropic's model for hard, long-running AI tasks, with a 1 million-token context window, a maximum output of 128,000 tokens, adaptive thinking, stronger agentic coding and research capabilities, and cheaper cache reads. Anthropic's published benchmarks show gains over Fable 5 in scientific research, coding, knowledge work, computer use, business workflows, and reasoning. Results still vary across benchmarks, and real-world performance depends on the task and testing conditions.
For builders, benchmarks are only one part of the picture. What matters more is how you put the model to work on something real, like an internal tool or a customer-facing app. That is where Emergent comes in. Claude Fable 5.1 is now available on Emergent for work that needs sustained reasoning, tool use, and the ability to check results over longer sessions. You can use it through your Emergent credits to finish complex tasks with less supervision, instead of just generating responses.
Most AI app builders stop at prototypes. Emergent creates production-ready apps you can actually launch.
- Production-ready apps
- Web & mobile apps
- Deploy in minutes